你的编程智能体把你变成了管理者
Your coding agents made you a manager
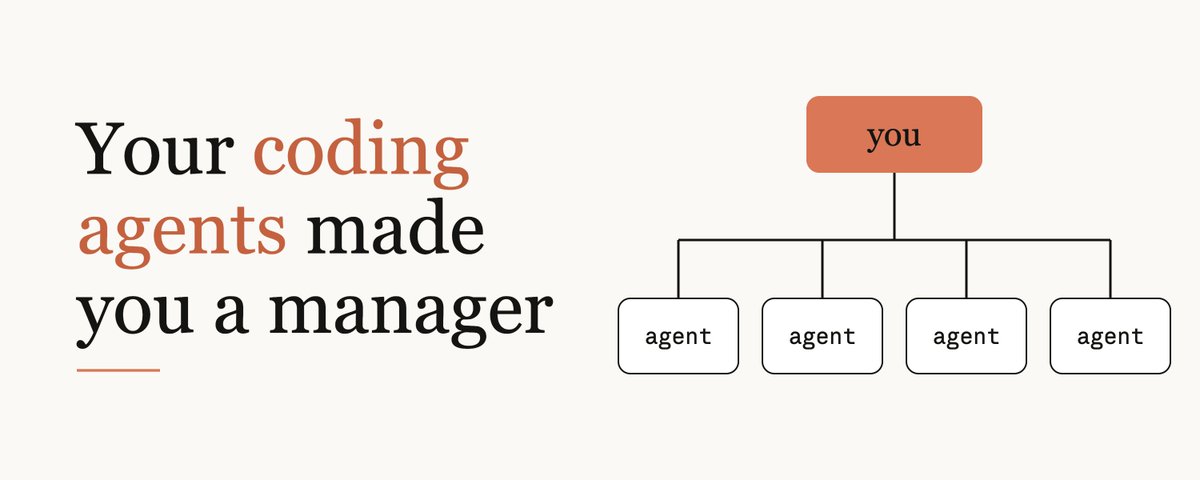
*The skills for managing agents are pretty much the skills for managing a team, and you don't need to be a manager to learn them.*
If you're spending all day with a coding agent, you are managing. You're repeatedly selecting tasks, writing instructions, delegating, following up, evaluating results, and deciding what ships. The engineers who get the most out of agents aren't necessarily the ones who are best at prompt engineering. They're the ones who learned how to manage, intentionally or otherwise.
This might be an unwelcome idea. Many of the engineers I admire took an individual contributor (IC) career path because they want to stay close to the work. They've seen friends become managers and disappear into their calendars. But I'm not telling you to become a manager like that. I'm using "management" in a specific sense: producing good outcomes by enabling others' work. And I'm certainly not saying agents are a substitute for managers or colleagues.
Every gripe you have about bad managers is a bug report for interacting with agents. Think about handoffs. If you’ve experienced a bad one you may have got an ask that felt vague, lacked context or just had expectations shift a lot. The good news for ICs is that since you’ve been on the receiving end of handoffs for years, you might know what a good one looks like.
I've written before that your coding agents need a manager. I've also written about the quiet risk of delegation, cognitive surrender. This piece compares good engineering managers' practices with what we've learned from using and creating Claude Code. The sections are roughly ordered by impact, so that the most high-leverage habit comes first.
Give it a way to check its work
Best practice: Provide the agent with a mechanism to validate its work, like a test suite, build, or screenshot, and have it show you the results as proof.
Anti-pattern: Taking "looks done" as confirmation. This forces you to do all the validation, becoming the agent's test suite.
Ask an experienced manager how they can be confident their team is producing good work without reading everything, and they'll talk about guardrails. CI, code review, dashboards, on-call, etc. Inexperienced managers who don't build guardrails end up validating everything themselves, and within a quarter they're the bottleneck. The same is true for agents. As the Claude Code best-practices guide explains, agents stop when the work looks done. If there's no validation, "looks done" is the only validation the agent has. Providing a mechanism to validate the work allows the agent to do the work, run the validator, see the failure, and correct it on its own. For a UI change, this can mean actually opening the page in a browser and iterating until it works and looks good.
The validation mechanism can be almost anything, as long as it's something that yields a definitive pass/fail result. Think tests, build exit codes, linters, diff scripts, and screenshots. The guide notes that the command that runs these validations is the single most useful line you can have in your CLAUDE.md, the instructions file the agent starts each session with. Once you have the validation mechanism, here are some ways you can bring it into your workflow:
- Ask. "Run the auth tests after, and continue until they pass."
- Set a goal. With /goal, a separate model runs a condition check after every turn, which is most useful when doing long background work.
- Enforce. A Stop hook can prevent the turn from completing until the typecheck passes.
- Have it reviewed. /code-review sends the diff to a new subagent (which didn't see your conversation) for review, like how authors don't approve their own PRs.
You can even control the scope of the review. If you ask it to find problems, it will always find something. But if you ask it to find correctness issues and ignore style, it will do that. This is how good managers learn to ask for feedback, as well. Most of the functionality in the Claude Code toolkit is all about tightening this loop. Skills, hooks, subagents, and MCP all exist to bridge the gap between doing the work and validating the work, so your focus is only on the things the agent couldn't validate. This is what experienced engineering managers do.
Set clear context
Best practice: Provide a clear summary of what the agent can't know by inspecting the repo, including: the task's objective and why it's important, constraints, out-of-scope items, and success criteria.
Anti-pattern: Passing a one-line task, while the real expectations live in your head, or padding the brief with things the agent would discover by reading the code.
Effective managers provide clear descriptions of the desired outcome, constraints, and objectives. They articulate what the work should accomplish, but give the person doing the work the freedom to figure out how to do it. In the military, they call it commander's intent. At Netflix, they call it "context, not control."
The challenge of working with agents is that it's hard to know what context the agent is missing. The first thing a coding agent does on every task is read your code. Current models are fantastic at picking up on your folder structure, conventions, and test set-up much faster than you could describe them.
Before you write anything down, think about what the agent can figure out on its own. If the agent can read it in your code, and it would actually go read it, you don't need to say anything. Spend your words on the parts that are not in the repo - e.g. a meeting decision, someone's internal process for deploying, why this task is important, and what it means to be done this time.
Let's take the example of a vague task, "make the dashboard faster", and turn it into a prompt. The numbers here are just for example.
Get p95 load time for the /team dashboard under 2s for orgs with 10k+ members.

Why: enterprise admins open it daily, and slow loads are their top support ticket.

Constraints: no schema changes; keep the API response shape.

Out of scope: UI changes; caching the whole page.
Check: run scripts/perf/team.sh and show before and after numbers.
You don't need to do this for every task. If you're doing discovery work, it's totally fine to write a generic prompt. You'll just refine a little more as you go. If you're not ready to write a prompt, have the agent interview you until it could write the spec, save that spec to a file, and then start a new session with the agent to build from that. You can use that spec to review against later.
You might also need to give your agent access to other tools, like your issue tracker, error dashboard, or team chat. Treat your agent the same way you'd treat a new hire on your team. If it's a CLI tool it already knows about, like gh, you often won't need to tell it anything.
Make every correction compound
Best practice: When you correct the same thing more than once, document it in the team's CLAUDE.md or turn it into a shared skill. Over time, check if newer models reduce the need for these corrections.
Anti-pattern: Manually correcting the same thing every session or relying on tacit knowledge that only exists on your own machine.
Teams that maximize the value of CLAUDE.md update it semi often and write down lessons learned from mistakes worth preventing. Some teams even mention @claude in code reviews, turning feedback into a permanent policy. Keep CLAUDE.md concise. Here are the types of things that belong in it:
- How to verify something (exact commands)
- Misleading areas of the code
- Decisions that don't exist in the repo
- Anything you've corrected twice
These are all examples of the compounding nature of written information. It outlasts people changing teams and models getting replaced.
Let it decide, and enforce only what can't bend
Best practice: Let the agent decide by default and only use hard enforcement (e.g. hooks, deny rules) for the few things that must always or never happen.
Anti-pattern: You write rules in ALL CAPS, define hooks for optional preferences, or keep habits from older models long after newer models outgrew them.
Andy Grove's *High Output Management* describes this as task-relevant maturity: the level of supervision should depend on a person's history of performance in that specific task, not their overall capability.
An old piece of advice for new managers says the same thing: give people a little more latitude than you're comfortable with while backing them up and holding them accountable.
Claude Code takes this and makes it explicit: prompts, CLAUDE.md, and skills are requests that the model can consider and choose to act on; hooks, deny rules, and managed settings are requirements that are always enforced. In most cases, you want the agent to make the call. There are often cases where the model, looking at real code, is better placed to judge if a guideline applies than a rule you set ahead of time. Use enforcement to set hard requirements such as "never edit the generated client" or "always run the license-header script." In particular, new terminal and VS Code sessions start in auto mode, with a classifier that will filter out unsafe behaviors like deploying to production or force pushing over someone's work.
The guide's advice has two sides. If you're putting more emphasis on a CLAUDE.md line and the agent still isn't picking it up, it should be a hook. If a hook is expressing a preference instead of a requirement, it should be removed in favor of letting the agent call the shots. It's like your team deciding to retire a process that is no longer useful. This also means adjusting when you have a new model. The guide keeps a list of habits you can stop: ALL CAPS directions, "think harder" (effort is a setting now), and "don't be lazy." With current models, these tend to lead to over-enforced rules and overwork. With agents, over-process is the new micromanagement.
Plan before it builds
Best practice: Set an agreed-upon plan before the agent starts coding, read for underlying assumptions, and partition tasks into non-overlapping parallel work.
Anti-pattern: Allowing multiple agents to tackle overlapping tasks simultaneously, then spending the afternoon resolving merge conflicts and duplicated decisions.
A good workflow here is to first enter plan mode and iterate on your plan until you have the right one, then delegate the coding. With a good plan, the model can often build it all in a single pass. For larger tasks, use a second session to look through the plan as a staff engineer would; it's a design review, which is the cheapest place to catch a wrong turn. When reviewing the plan, look for underlying assumptions (in a 1:1 this would be asking, "What are you unsure about?").
Decomposition is increasingly being delegated to agents. /batch in Claude Code takes a big mechanical change and creates 5 to 30 tasks, displays the plan, executes them in separate worktrees (separate checkouts of the repo), and creates a PR for each one. You no longer need to divide up the work, just check the slices for overlap and make sure shared interfaces land first. Without this, you might get a false level of parallelism. Five agents taking on overlapping tasks won't lead to five times the output, it leads to one merge conflict with five authors.
Steer early, reset fast
Best practice: Watch the first minute and steer the agent. As soon as you see it go off course, correct. If you've already made two failed attempts to correct the agent, start anew with a fresh session and better prompt.
Anti-pattern: Adding a third or fourth attempt to correct the agent, instead of correcting the request.
An experienced manager knows that if a capable person has a miss multiple times, the problem might be upstream with the instructions, context or scope. The agent version is explicit: as soon as the agent goes off course, hit Esc. If you've already made two failed attempts to correct the agent, clear the session and write a better prompt, incorporating the lessons you learned. A third attempt to correct the agent is mostly just more information that the model has to keep re-reading and re-processing (including failed attempts).
Cheap rollback is also changing the game. /rewind rolls the code and conversation to an earlier point, making it low-risk to try a more ambitious approach first. Good managers do the same with employees: if undoing a mistake is cheap, let them try an ambitious approach. Then run the retro afterwards, and generalize the fix into CLAUDE.md if applicable.
Delegate the task, never the judgment
Best practice: The agent does the work, you decide the important things: product calls, security boundaries, what ships. Treat every diff like you're going to get paged for it.
Anti-pattern: Approving large diffs because the tests are green and the names look reasonable. This is not code review, this is code ratification.
No manager can say "my report shipped that, not me." The same is true for every agent you run. I've fallen into this trap myself. I told an agent to research gaps with competitors and write local PRs to close those gaps. I read the research, skimmed the code and almost went ahead and pushed changes that added complexity for users for little gain. I had delegated the work, and almost delegated the decision as well. It's an easy trap to fall into: it's a 600-line diff, the names look reasonable, the tests are green, approve.
It makes sense to split tasks this way: let agents do the style, linting, follow-ups to reviews, typical bugs and unit testing, but let humans handle security boundaries, compliance and product decisions.
Coordination works the same way. An agent can keep track of handoffs, but deciding between competing requests and getting people to actually commit is still a human job.
You don't need to be in the inner loop of every change. What you do need to own are the outer loops: what the constraints are, how much of the output you actually read, what evidence you keep, and what a human has to sign off on. And keep changes small, since the unit of review is the unit of comprehension.
Design the run that doesn't need you
Best practice: Before deploying an autonomous task, define done, the self-verification, the boundaries, the guardrails, and the human approval.
Anti-pattern: Starting a long-running process before bed, without a definition of done or a stopping point, and waking up the next morning to find out that your model has been working overnight on a faulty premise.
Skip-level managers don't manage the work of individual engineers; they manage the work of goals, guardrails, checkpoints, and leads. AI agents are following a similar trajectory. They are already delegating parts of a task to sub-agents, and they can run autonomously on schedules, after CI failures or after new pull requests are opened. The frontier is self-governing systems that can autonomously start, self-verify, and only call for human intervention when decisions are needed.
The role shifts from controlling the session to designing your loops. The five questions to ask yourself when designing an unattended run are the same questions a good manager asks before giving a senior engineer a project and going on vacation:
- Does it know what done looks like? (Goal condition, spec file, or a failing test it has to turn green.)
- Does it have a self-verification mechanism? (Test suite, Stop hook, or review step.)
- What are its boundaries? (Permission controls, sandbox, worktree, or the one branch it's allowed to push to.)
- What are its guardrails? (Turn limit or spend limit.)
- Where does it produce output, and who approves it? (A PR or summary, and a human approval of any non-reversible actions.)
The guide has two more habits that managers will recognize as good practices: pilot, i.e., get a batch job to run on three files, iterate the prompt, then run the rest; and watch the first few runs of anything new before you trust it unattended. Think of it as a probation period.
Scale verification, not attention
Best practice: Scale up the use of agents only as fast as checks, goals and fresh reviewers can take over the watching, and measure quality in addition to throughput.
Anti-pattern: Opening more sessions than you can review well, and measuring success by how much code the AI wrote.
Managers learn their span of control pretty quickly. Past a certain number of direct reports, everyone gets less of the manager and the quality goes down. The same is true for agents. It's what I call the orchestration tax: Past the first few agents, each additional agent requires more of your attention than the last. Most days I run four or five background agents and a few local sessions, and some days that's too many.
Managing lots of sessions isn't about being super-focused, it's about delegating most of the monitoring to self-evaluation, goals and new-context reviewers and reserving attention for decisions. It also helps to have notifications instead of polling and a centralized view of the background jobs. You can't scale the number of agents by monitoring more, only by needing to monitor less. Then measure the system rather than the activity. Useful metrics include cycle time for PRs, ramp up time for new employees and the frequency of reverts or rework. Measuring the percentage of AI-written code isn't a useful goal, because what you're aiming for is quality and reliability. Grove's rule of measuring with a countermeasure applies here: If you measure the number of PRs merged, then also measure reverts and rework.
Decide what not to build
Best practice: Ask who needs it, how you'll know it worked and what would make you stop, and limit WIP.
Anti-pattern: Just throwing every plausible idea into a PR; after all it's cheap to build. You'll now have a junk drawer the team needs to review, secure and maintain.
The most important word a manager says is often "no." With agents, it's harder to say no. It's nearly free to start work and you can throw any plausible idea into a PR by lunch. But you'll now have a bunch of PRs that the team needs to review, secure, support and maintain. Review and validation are the scarce resources now.
In fact, the old management questions matter now more than they used to. Who asked for it? How do we measure success? How do we know when to stop? If it's cheap to build the hard question is not "can we?" but "should we?"
Where the analogy breaks
Best practice: Follow management best practices, but account for the differences in the agent model, like cheap rework, how quick they are to agree, and strengths that shift with every model release.
Anti-pattern: Thinking that an agent is just like a junior developer, or that you're prepared to manage five people because you can run five agents.
The analogy is a useful but imperfect one, and the best practitioners of this work are aware of where it is imperfect:
- Managing people is harder, and the skills don't transfer back. You're not prepared to manage five people because you've run five agents. There is no equivalent for motivation, conflict, career development, or months-long trust building.
- Rework is almost free. You can ask an agent things you would never ask of a person. If a technical debate happens at the whiteboard, the agent can build two or three options and you can compare them.
- Agents don't have experience, just a notebook. Auto memory only records notes on one machine. They don't transfer to your teammates' sessions. They aren't the experience and judgment you develop over the course of your career, and you need to write those lessons down for the whole team.
- Agents are eager and confident. If you ask a good engineer to do something wrong, they push back. Agents are more likely to do what you ask, and you're likely to overtrust them. In Wharton research on cognitive surrender, participants accepted faulty AI answers most of the time, and grew more confident. You can counter the overconfidence by asking the agent to argue against its own answer.
- You only have one agent archetype, and it changes every few months. Human teams have diverse skills and strengths. All your agents have the same strengths and weaknesses, which shift with each model release.
- You still have to train your junior devs. When agents take over the starter work junior devs need to learn the fundamentals of the craft, you have to create those reps intentionally as a manager.
- The human team still matters. Sometimes you can spend a day managing agents without realizing that you've crowded out the time it takes to build a cohesive team. Don't do this.
You don't need the title
Best practice: Focus your effort on making good software happen: setting the context, defining done, and reviewing well.
Anti-pattern: Evaluating yourself by lines of code while running under-briefed, unchecked agents.
Good staff engineers have always been like this. They write the design doc. They set the context. They do a thorough review. They make the people around them better. Agents let all engineers do this on day one. They give you a crash course on management. You get feedback in minutes, not quarters. You can undo your own mistakes. The job is becoming less about writing the code and more about being the reason good code gets written.
Nobody's born a great manager (or a great engineer). You build skills the same way you always have, through practice. But with agents, practice is cheap.
Try these ideas:
- Every task needs a check it can run. Ask for the proof.
- Tell the agent what it can't see and leave out what it can.
- Talk through the plan before writing the code.
- Corrected something twice? Log it in CLAUDE.md. Repeated workflows? Turn them into skills.
- Two failed corrections? Restart and rephrase the prompt.
- Review the diff as if you'll get paged for it.
You don't have to want to be a manager. But the engineers who do well with agents will have learned to manage along the way.
*管理智能体的技能,几乎就是管理团队的技能,而学习这些技能并不需要你成为管理者。*
如果你整天都在和编程智能体打交道,那你就是在做管理。你在反复挑选任务、撰写指令、委派工作、跟进进展、评估结果,并决定哪些成果可以交付。最善于利用智能体的工程师,未必是提示词工程最强的人,而是那些学会如何管理的人——无论是有意还是无意。
这个想法可能不太受欢迎。我敬佩的许多工程师选择个人贡献者(IC)的职业道路,是因为他们想贴近实际工作。他们见过朋友当上管理者后,整个人消失在日历里。但我不是在劝你成为那样的管理者。我所说的“管理”有特定含义:通过让他人的工作得以开展来产生好结果。我也绝不是说智能体可以取代管理者或同事。
你对糟糕管理者的每一句抱怨,都是与智能体协作时的一份缺陷报告。想想交接。如果你经历过糟糕的交接,可能收到过含糊的请求、缺少上下文,或者期望值反复变化。对个人贡献者(IC)来说好消息是:多年来你一直处在交接的接收端,所以你也许知道好的交接长什么样。
我之前写过,你的编程智能体需要一位管理者。我也写过委派的隐性风险——认知投降。本文把优秀工程管理者的做法,与我们在使用和打造 Claude Code 过程中学到的东西进行比较。各章节大致按影响力排序,因此杠杆率最高的习惯排在最前面。
给它一种核验工作的方式
最佳实践: 为智能体提供一种验证其工作的机制,比如测试套件、构建或截图,并让它把结果展示给你作为证明。
反模式: 把“看起来完成了”当作确认。这会迫使你承担所有验证工作,让你变成智能体的测试套件。
问问一位经验丰富的管理者,在不读完全部内容的情况下,他们如何确信团队的工作质量,他们会谈到护栏。CI、代码评审、仪表盘、值班等等。不建立护栏的新手管理者最终只能亲自验证一切,一个季度内就会成为瓶颈。智能体也是如此。正如 Claude Code 最佳实践指南 所解释的,智能体在工作看起来完成时就会停下。如果没有验证,“看起来完成了”就是智能体唯一的验证。提供验证工作的机制,能让智能体完成工作、运行验证器、看到失败,并自行修正。对于 UI 改动,这可能意味着真正在浏览器中打开页面,不断迭代,直到它能正常工作且看起来不错。
验证机制几乎可以是任何东西,只要它能给出明确的通过/失败结果。比如测试、构建退出码、linter、差异(diff)脚本和截图。该指南指出,运行这些验证的命令是你在 CLAUDE.md 中能写下的最有价值的一行——CLAUDE.md 是智能体每个会话开始时都会读取的指令文件。有了验证机制后,以下是一些把它融入工作流的方法:
- 直接要求。“之后运行认证测试,并持续直到通过。”
- 设定目标。 使用 /goal 时,另一个模型会在每一轮之后运行条件检查,这在执行长时间后台工作时最有用。
- 强制执行。 Stop 钩子可以阻止该轮完成,直到类型检查通过。
- 让它接受评审。 /code-review 会把差异(diff)发送给一个新的子智能体(它没有看过你的对话)进行评审,就像作者不会批准自己的 PR 一样。
你甚至可以控制评审的范围。如果你让它找问题,它总能找到点什么。但如果你让它只找正确性问题、忽略风格,它就会照做。优秀的管理者也是这么学会征求反馈的。Claude Code 工具包中的大部分功能都是围绕收紧这个循环。技能、钩子、子智能体和 MCP 的存在,都是为了弥合“做工作”和“验证工作”之间的差距,让你的注意力只放在智能体无法验证的事情上。这正是经验丰富的工程管理者所做的。
设定清晰的上下文
最佳实践: 清楚说明智能体无法通过检查代码仓库得知的内容,包括:任务目标及其重要性、约束条件、范围之外的事项,以及成功标准。
反模式: 只丢下一行任务,而真正的期望只存在于你脑子里;或者用智能体读代码就能发现的内容来填充任务说明。
高效的管理者会清楚描述期望的结果、约束和目标。他们阐明工作应达成什么,但把如何完成的自由交给执行者。在军队里,这被称为指挥官意图。在 Netflix,这被称为“提供上下文,而非控制”。
与智能体协作的挑战在于,很难知道智能体缺少哪些上下文。编程智能体在每个任务中做的第一件事就是阅读你的代码。当前的模型非常擅长捕捉你的文件夹结构、约定和测试设置,速度远比你描述它们要快。
在动笔之前,先想想智能体能自己弄清楚什么。如果智能体能从你的代码中读到,而且它确实会去读,那你就不必说什么。把话用在仓库之外的部分——例如某次会议的决定、某人内部的部署流程、这个任务为什么重要,以及这次“完成”意味着什么。
我们以一个含糊的任务为例——“让仪表盘更快”——把它改写成提示词。这里的数字只是示例。
Get p95 load time for the /team dashboard under 2s for orgs with 10k+ members.

Why: enterprise admins open it daily, and slow loads are their top support ticket.

Constraints: no schema changes; keep the API response shape.

Out of scope: UI changes; caching the whole page.
Check: run scripts/perf/team.sh and show before and after numbers.
你不需要对每个任务都这样做。如果你在做探索性工作,写一个通用提示词完全没问题,边做边再细化一点即可。如果你还没准备好写提示词,可以让智能体采访你,直到它能写出规格说明;把该规格说明保存到文件,然后与智能体开启一个新会话,基于它来构建。之后你可以用这份规格说明作为评审依据。
你可能还需要让智能体访问其他工具,比如问题跟踪系统、错误仪表盘或团队聊天。像对待团队新员工一样对待你的智能体。如果是它已经了解的 CLI 工具,比如 gh,通常你什么都不用告诉它。
让每一次纠正都能累积
最佳实践: 当你对同一件事纠正不止一次时,把它记录到团队的 CLAUDE.md 中,或把它变成共享技能。随着时间推移,检查更新的模型是否减少了对这些纠正的需求。
反模式: 每个会话都手动纠正同一件事,或依赖只存在于你自己机器上的隐性知识。
能最大化 CLAUDE.md 价值的团队会经常更新它,并记下那些值得防范的错误教训。有些团队甚至会在代码评审中 @claude,把反馈变成永久策略。保持 CLAUDE.md 简洁。以下是适合写入其中的内容类型:
- 如何验证某件事(确切命令)
- 代码中容易误导人的部分
- 仓库中不存在的决策
- 任何你纠正过两次的事情
这些都是书面信息具有累积效应的例子。它比人员换团队、模型被替换更持久。
让它做决定,只对不可变通的事强制执行
最佳实践: 默认让智能体做决定,只对少数必须始终发生或绝不能发生的事使用硬性约束(例如钩子、拒绝规则)。
反模式: 你用全大写写规则,为可选偏好定义钩子,或者在更新的模型早已不再需要后仍保留旧模型的习惯。
安迪·格鲁夫的*《高产出管理》*把这一点描述为任务相关成熟度:监督的程度应取决于一个人在该特定任务上的过往表现,而非其整体能力。
给新管理者的一条老建议也是这个意思:给别人比你感到舒适稍多一点的空间,同时支持他们并让他们承担责任。
Claude Code 采纳了这一点并把它明确化:提示词、CLAUDE.md 和技能是模型可以考虑并选择执行的请求;钩子、拒绝规则和受管设置是始终强制执行的硬性要求。大多数情况下,你希望让智能体自己做决定。很多时候,模型面对真实代码,比你预先设定的规则更能判断某条准则是否适用。用强制执行来设定硬性要求,比如“绝不要编辑生成的客户端代码”或“始终运行许可证头脚本”。特别是,新的终端和 VS Code 会话以自动模式启动,其中有一个分类器会过滤掉不安全的行为,比如部署到生产环境或强推覆盖别人的工作。
这份指南的建议有两面性。如果你越来越强调 CLAUDE.md 中的某一行,而智能体仍然没有领会,那它就应该改成一个钩子。如果一个钩子表达的是偏好而不是要求,就应该把它移除,转而让智能体自行决定。这就像你的团队决定淘汰一个不再有用的流程。这也意味着当你有了新模型时要做出调整。指南列出了一份可以停止的习惯清单:全大写指令、“再努力想想”(现在努力程度是一个设置项),以及“别偷懒”。对于当前模型,这些做法往往会导致规则被过度执行、工作负荷过大。在智能体时代,过度流程化就是新的微观管理。
先规划,再构建
最佳实践: 在智能体开始编码前先确定一份各方认可的计划,审视其中的潜在假设,并把任务划分为互不重叠的并行工作。
反模式: 允许多个智能体同时处理相互重叠的任务,然后花一下午解决合并冲突和重复的决策。
一个好流程是先进入计划模式,反复迭代计划,直到得到合适的版本,然后再委派编码。有了好的计划,模型往往能一次完成全部构建。对于更大的任务,可以另开一个会话,像资深工程师(staff engineer)那样通读计划;这是一次设计评审,也是发现方向错误成本最低的地方。评审计划时,要留意潜在假设(在一对一沟通中,这相当于问:“你有什么不确定的地方?”)。
任务拆解正越来越多地交给智能体。Claude Code 中的 /batch 会接收一项大型机械性变更,创建 5 到 30 个任务,展示计划,在各自独立的工作树(仓库的独立检出)中执行任务,并为每个任务创建一个 PR。你不再需要亲自划分工作,只需检查各任务切片是否重叠,并确保共享接口先行落地。否则,你可能会得到一种虚假的并行程度。五个智能体接手相互重叠的任务,不会带来五倍产出,只会带来一个涉及五位作者的合并冲突。
尽早引导,快速重置
最佳实践: 盯住第一分钟并引导智能体。一旦发现它偏离方向,就立即纠正。如果你已经两次尝试纠正智能体但都失败,就用全新会话和更好的提示词重新开始。
反模式: 第三次、第四次尝试纠正智能体,而不是修正请求本身。
有经验的管理者知道,如果一个有能力的人多次失手,问题可能出在上游的指令、上下文或范围。在智能体场景下,规则很明确:一旦智能体偏离方向,就按 Esc。如果你已经两次尝试纠正智能体但都失败,就清空会话,并写出更好的提示词,把学到的经验融入其中。第三次尝试纠正智能体,大多只是给模型增加更多需要反复阅读和重新处理的信息(包括失败的尝试)。
低成本回滚也在改变游戏规则。/rewind 会把代码和对话回滚到更早的时间点,让先尝试更大胆的方案成为低风险选择。优秀的管理者对员工也是如此:如果纠正错误的成本很低,就让他们尝试大胆的方案。之后再复盘,并在适用时把修复经验归纳到 CLAUDE.md 中。
委派任务,绝不委派判断力
最佳实践: 智能体负责执行,你来决定重要事项:产品决策、安全边界以及什么可以发布。对待每个差异(diff),都要像自己会因它被紧急呼叫一样。
反模式: 因为测试全绿、命名看起来合理,就批准大型差异(diff)。这不是代码评审,而是在给代码盖章放行。
没有哪个管理者能说“是我的直接下属发布了它,而不是我”。你运行的每个智能体也是如此。我自己也掉进过这个陷阱。我让一个智能体研究我们与竞争对手之间的差距,并编写本地 PR 来弥补这些差距。我读了研究报告,浏览了代码,差点就继续推送了那些给用户增加复杂性却几乎没有收益的变更。我委派了工作,还差点把决策也一起委派出去。这个陷阱很容易掉进去:一个 600 行的差异(diff),命名看起来合理,测试全绿,批准吧。
按这种方式拆分任务是合理的:让智能体处理代码风格、lint、评审后的跟进、常见缺陷和单元测试,而由人类处理安全边界、合规和产品决策。
协调也是如此。智能体可以跟踪交接事项,但在相互竞争的请求之间做选择,并让人们真正投入承诺,仍然是人类的工作。
你不需要身处每一次变更的内环。你真正需要掌控的是外环:约束条件是什么、你实际会阅读多少产出、你保留哪些证据,以及哪些事情必须由人类签字确认。同时要让变更保持小规模,因为评审的单位就是理解的单位。
设计无需你介入的运行流程
最佳实践: 在部署自主任务之前,先定义完成标准、自我核验方式、边界、护栏和人工审批。
反模式: 睡前启动一个长时间运行的流程,却没有完成定义或停止点,第二天早上醒来才发现模型整夜都在错误的前提上工作。
跨级管理者不管理单个工程师的工作;他们管理的是目标、护栏、检查点和团队负责人。AI 智能体正沿着类似的轨迹发展。它们已经在把任务的部分工作委派给子智能体,并且可以按计划、在 CI 失败后或在新拉取请求创建后自主运行。前沿是自治系统:它们能自主启动、自我核验,并且只在需要决策时才请求人类介入。
角色从控制会话转向设计你的循环。设计无人值守运行时,要问自己的五个问题,正是一个优秀管理者在把项目交给资深工程师然后去度假前会问的同样问题:
- 它知道完成是什么样子吗?(目标条件、规格说明文件,或一个必须由它转绿的失败测试。)
- 它有自我核验机制吗?(测试套件、Stop 钩子或评审步骤。)
- 它的边界是什么?(权限控制、沙箱、工作树,或唯一被允许推送的分支。)
- 它的护栏是什么?(轮次限制或支出限制。)
- 它在何处产出结果,由谁批准?(一个 PR 或总结,以及任何不可逆操作都需要人工审批。)
指南还提到两个管理者会认出是好做法的习惯:先试点,也就是让批处理任务先跑三个文件,迭代提示词,再运行其余部分;以及在放心让任何新事物无人值守之前,先观察它的最初几次运行。可以把它看作试用期。
扩大验证规模,而非注意力规模
最佳实践: 扩大智能体使用规模的节奏,只能与检查、目标和全新评审者能够接手监视工作的速度相匹配;并且除了吞吐量,还要衡量质量。
反模式: 开启超出你评审能力的会话,并以 AI 写了多少代码来衡量成功。
管理者很快就会摸清自己的管理幅度。当直接下属超过一定数量后,每个人分到的管理者精力都会变少,质量也会下降。智能体也是如此。这就是我所说的编排税:超过最初几个智能体后,每新增一个智能体,都会比上一个占用你更多注意力。大多数日子我会运行四五个后台智能体和几个本地会话,有些日子这已经太多了。
管理大量会话,关键不在于高度专注,而在于把大部分监控工作委派给自我评估、目标和拥有全新上下文的评审者,并把注意力留给决策。用通知代替轮询,并集中查看后台任务,也会有所帮助。扩展智能体数量不能靠监控更多,只能靠减少监控需求。然后,衡量系统,而不是活动。有用的指标包括 PR 周期时间、新员工上手时间,以及回滚或返工的频率。衡量 AI 编写代码的占比并不是一个有用的目标,因为你追求的是质量和可靠性。安迪·格鲁夫关于衡量时要配套反向指标的规则在这里同样适用:如果你衡量合并的 PR 数量,也要衡量回滚和返工。
决定不构建什么
最佳实践: 先问谁需要它、你如何知道它奏效,以及什么情况会让你停下来,并限制进行中的工作(WIP)。
反模式: 把每个看似可行的想法都直接扔进一个 PR;毕竟构建成本很低。现在你就有了一个杂物抽屉,团队得去评审、保障安全并维护它。
管理者说出的最重要的词往往是“不”。有了智能体后,说“不”变得更难。启动工作几乎不花成本,午饭前你就能把任何看似可行的想法扔进一个 PR。但你现在会有一堆 PR,团队需要评审、保障安全、提供支持并维护它们。评审和验证现在是稀缺资源。
事实上,那些经典的管理问题现在比过去更重要。是谁提出要做的?我们如何衡量成功?我们怎么知道何时停止?如果构建成本很低,那么难的问题就不是“我们能不能做?”,而是“我们该不该做?”
类比在哪里失效
最佳实践: 遵循管理最佳实践,但要考虑智能体这种模式的不同之处,例如返工成本低、它们很容易附和,以及每次模型发布都会改变的优势。
反模式: 把智能体当成初级开发者,或者因为你能运行五个智能体,就以为自己准备好管理五个人。
这个类比有用但不完美,而最优秀的实践者清楚它在哪里不完美:
- 管理人更难,而且这些技能无法反向迁移。 你能运行五个智能体,不代表你准备好管理五个人。动机、冲突、职业发展或耗时数月建立的信任,都没有对应的替代物。
- 返工几乎免费。 你可以让智能体做你绝不会要求别人做的事。如果一场技术辩论在白板前展开,智能体可以做出两三种方案,供你比较。
- 智能体没有经验,只有一本笔记本。 自动记忆只会在单台机器上记录笔记。这些笔记不会迁移到队友的会话中。它们不是你职业生涯中积累的经验和判断力,你需要为整个团队把这些经验教训写下来。
- 智能体积极又自信。 如果你让一位优秀工程师做错事,他们会提出异议。智能体更可能照你说的做,而你也更可能过度信任它们。在沃顿商学院关于认知投降的研究中,参与者大多数时候接受了错误的 AI 答案,而且变得更加自信。你可以让智能体反驳自己的答案,以此对抗这种过度自信。
- 你只有一种智能体原型,而且它每隔几个月就会变化。 人类团队拥有多样的技能和优势。你的所有智能体都有相同的长处和短处,而这些会随着每次模型发布而变化。
- 你仍然必须培养初级开发者。 当智能体接管了初级开发者学习这门手艺基础所需的入门工作时,你作为管理者必须有意识地创造这些练习机会。
- 人类团队仍然重要。 有时你可能花一整天管理智能体,却没意识到自己挤掉了建立有凝聚力团队所需的时间。不要这样做。
你不需要那个头衔
最佳实践: 把精力集中于促成优秀软件:设定上下文、明确完成定义、做好评审。
反模式: 一边运行交代不清、未经检查的智能体,一边用代码行数来评估自己。
优秀的资深工程师(staff engineer)向来如此。他们编写设计文档。他们设定上下文。他们做周全的评审。他们让身边的人变得更好。智能体让所有工程师在第一天就能做到这些。它们给你一堂管理速成课。你能在几分钟内获得反馈,而不是几个季度。你可以撤销自己的错误。这份工作正越来越不在于写代码,而更在于成为优秀代码得以写出的原因。
没有人生来就是优秀的管理者(或优秀的工程师)。你培养技能的方式一如既往:通过练习。但有了智能体,练习成本很低。
试试这些做法:
- 每项任务都需要一个可运行的检查。索要证据。
- 告诉智能体它看不到什么,省略它能看到的。
- 在写代码之前,先把计划讨论清楚。
- 同一个问题纠正了两次?把它记录到 CLAUDE.md 中。工作流反复出现?把它们变成技能。
- 两次纠正都失败?重新开始,并换个说法重写提示词。
- 像会因此被叫去处理故障一样审查差异(diff)。
你不必想成为管理者。但那些能借助智能体做出成绩的工程师,会在这一过程中学会管理。